LLM Provider
Choosing the built-in model or your own provider, and the web search switch.
The built-in engine
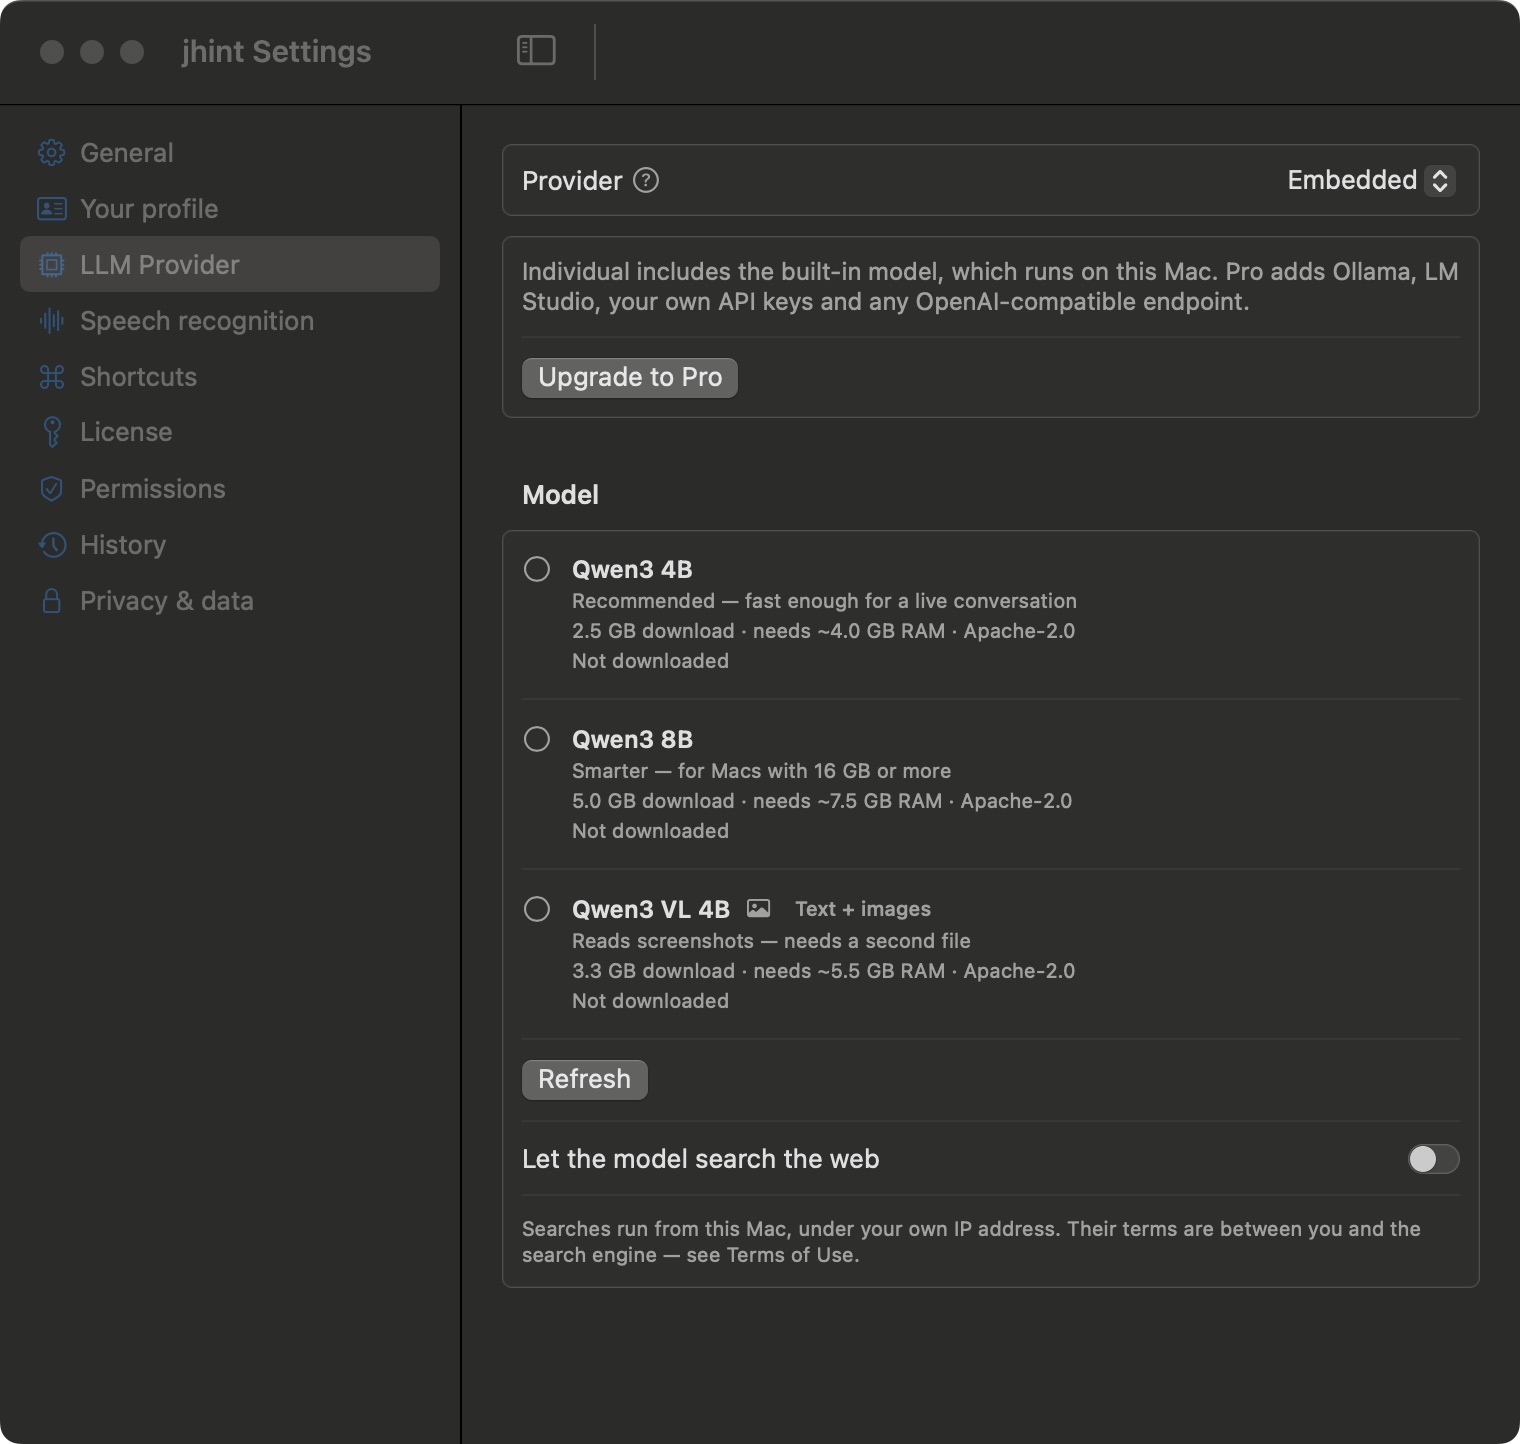
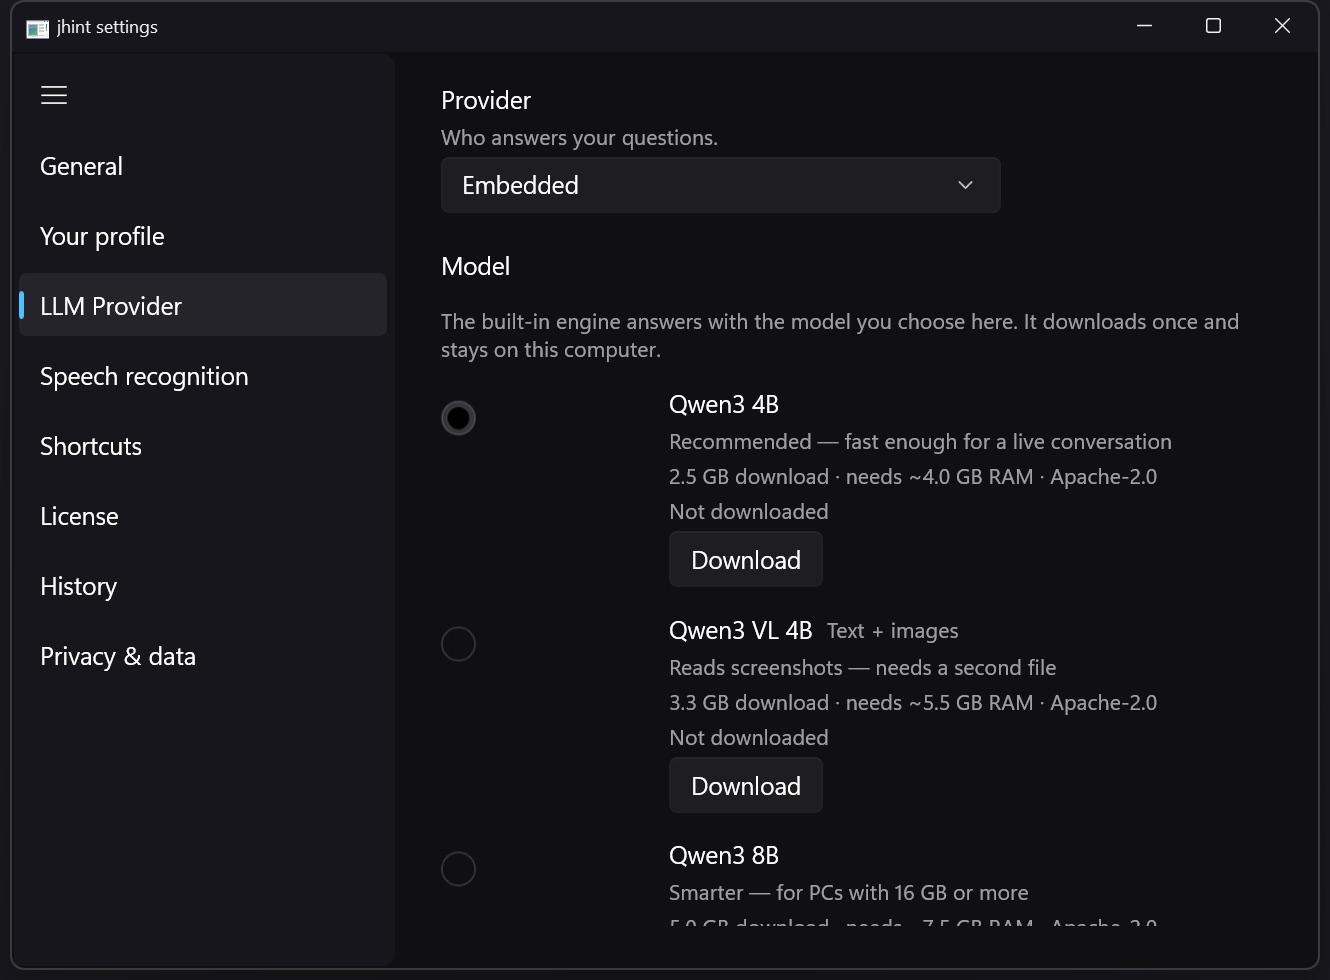
Each model states, before anything downloads, how big it is, how much memory it wants while it runs, and the licence it comes under. Not downloaded means exactly that — the app has the catalogue, not the weights.
A downloaded model can be deleted from the same list when you want the disk space back. The model you pick applies to the next session, not to a conversation already in progress.
Let the model search the web is the switch described on Web search. It is off until you turn it on.
Your own provider (Pro)
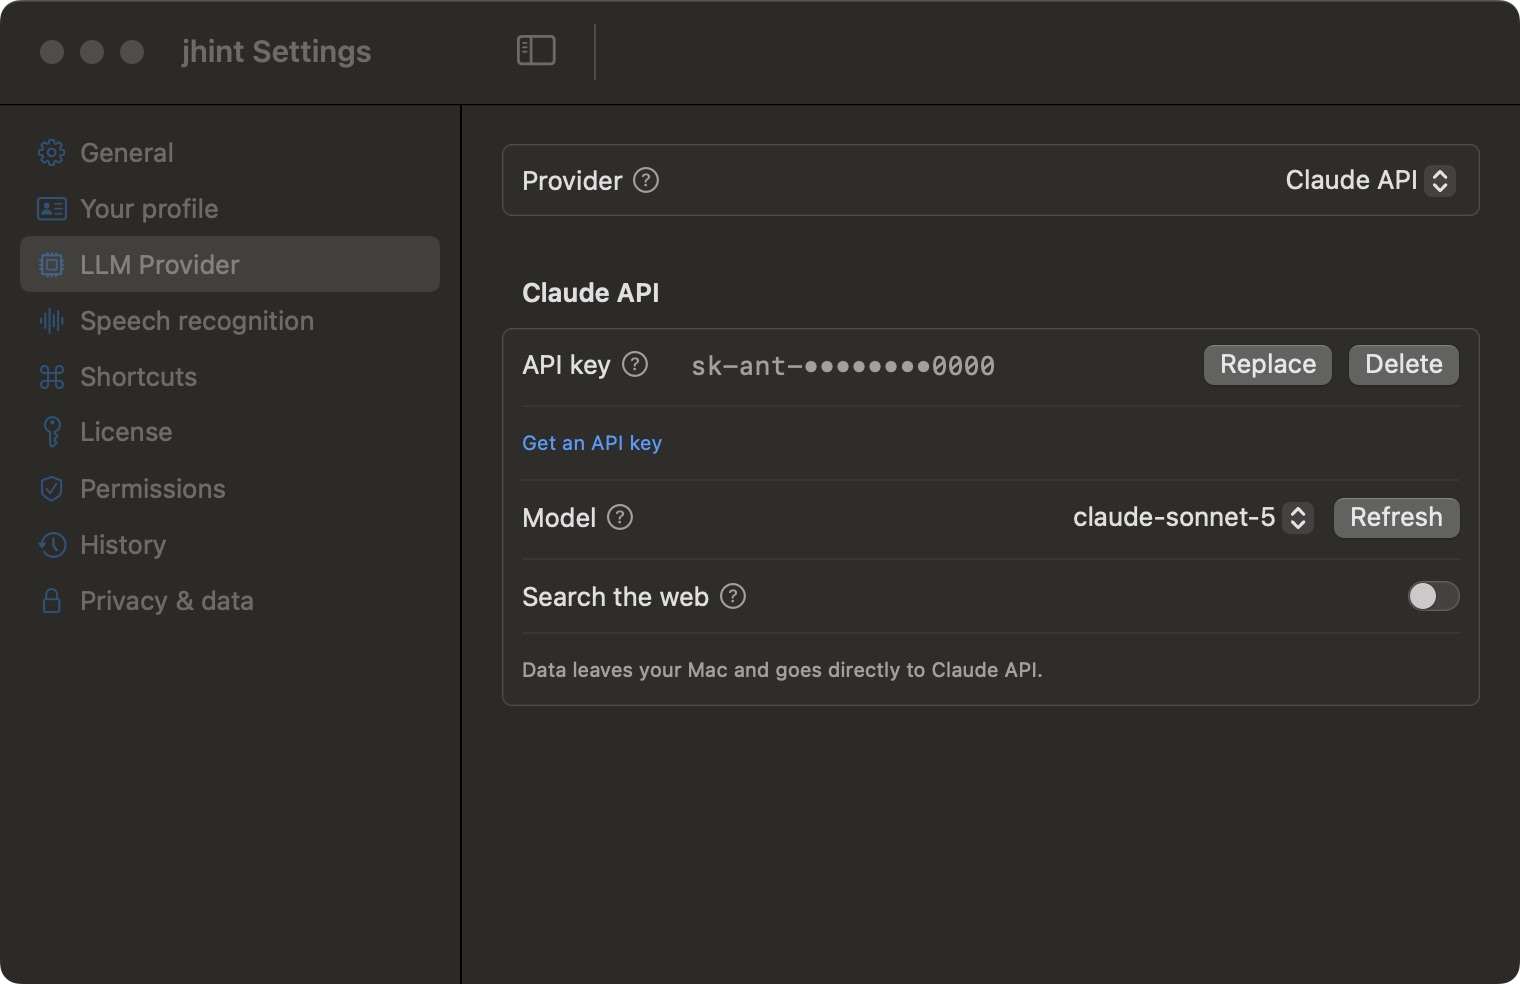
Everything below is part of Pro. On Individual the list still shows every provider, with the
ones outside your plan marked Pro and not selectable — and a line under the list says what Pro
adds, with an Upgrade to Pro button next to it (that is the block in the screenshot above
this section). Moving between plans is Settings → License → Change plan, and
Plans lists what each one includes.
If you move down to Individual while an external provider is selected, jhint switches you to the built-in model and offers Switch back to … here for as long as it makes sense — your key stays in your operating system’s protected credential storage either way — Apple Keychain on macOS, Windows Credential Manager on Windows.
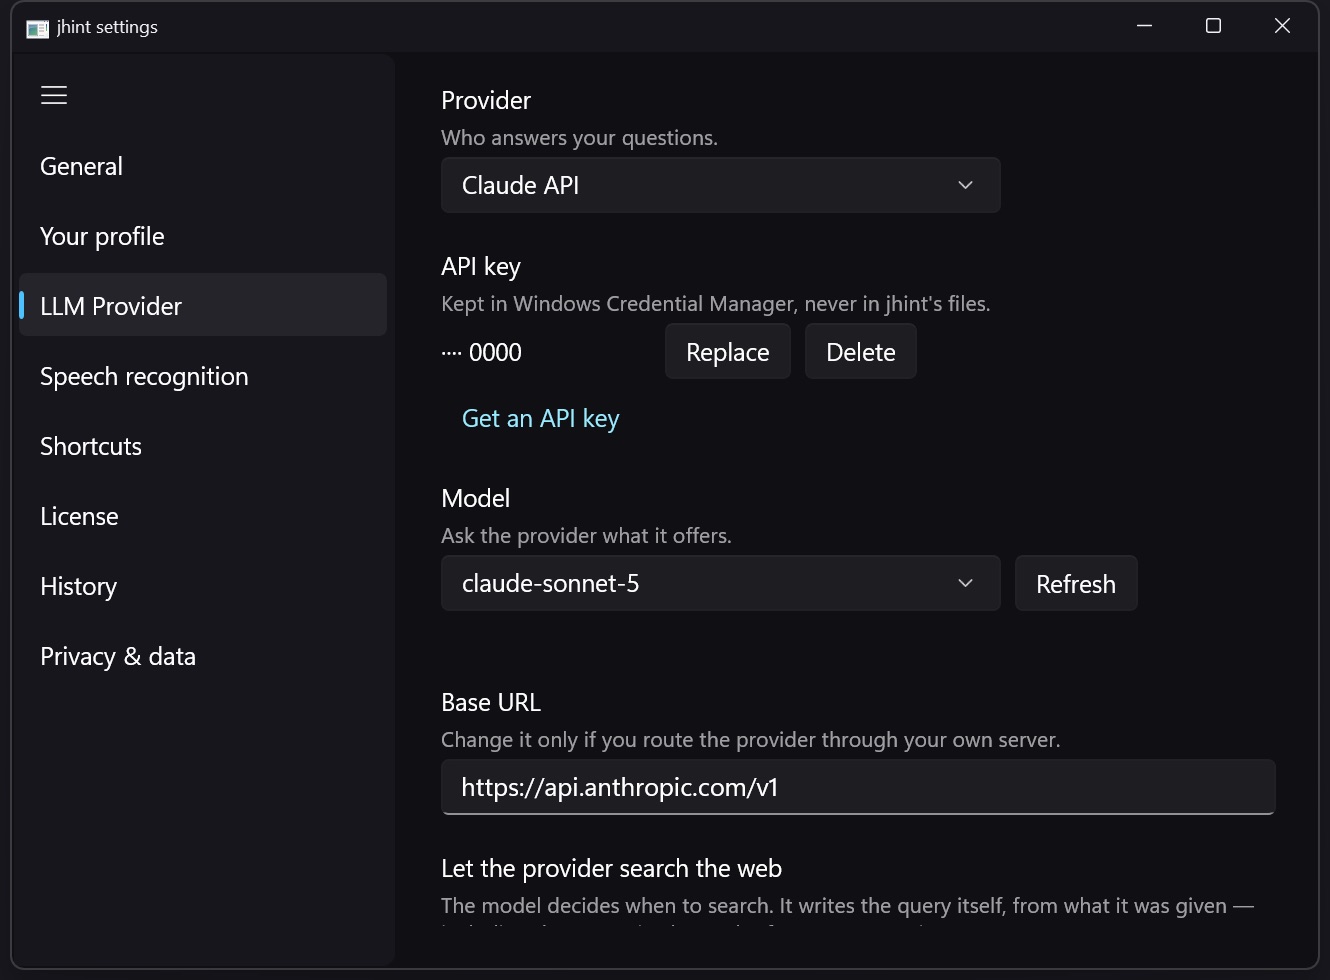
Pick a provider and paste the key. jhint stores it in the secure storage of your operating system and shows only its tail afterwards, so a screen share doesn’t leak it.
The model list is fetched from the provider itself, so it reflects what your account can actually use rather than a list we baked in months ago. Models that can read screenshots are marked; the rest have the capture button disabled.
Before the first external request, jhint tells you what will be sent and asks you to accept it. Until you do, nothing leaves the computer.
Ollama and LM Studio
Both are OpenAI-compatible: choose that provider and point jhint at the local address they serve on. No key, no external network — answers are computed by the machine running the model.